Start with the model
Model size, quantization and context all change memory needs. A GPU’s VRAM and a Mac’s shared memory describe different designs.
Real computers. Real creator tests. Find hardware for your work, inspect the exact configuration, and watch the evidence before you buy.
Model size, quantization and context all change memory needs. A GPU’s VRAM and a Mac’s shared memory describe different designs.
Private chat, coding, image generation and robotics need different software and hardware. An NPU alone does not guarantee model support.
A GPU needs a suitable host PC and power supply. A developer kit may need storage, cooling and setup. Check local warranty and current pricing.
Older systems remain useful budget choices. Newer hardware is included when a real local-model test is available.
30 researched options · Select up to three to compare
Compare (0/3)
Reviewed unit: M1 Mac mini with 16 GB memory; SSD unspecified.
Tested models
Llama 3 8B
Review by Bijan Bowen / Ominous Industries
See tests & buying guide
Reviewed unit:10-core M2 Pro Mac mini with 16 GB memory; SSD unspecified.
Tested models
Llama 3 8B
Review by Bijan Bowen / Ominous Industries
See tests & buying guide
Reviewed unit: M2 MacBook Air with 8 GB memory; GPU tier and SSD unspecified.
Tested models
Llama 3 8B
Review by Bijan Bowen / Ominous Industries
See tests & buying guide
Reviewed unit: M3 iMac with 16 GB memory; port/GPU tier and SSD unspecified.
Tested models
Llama 3 8B
Review by Bijan Bowen / Ominous Industries
See tests & buying guide
Reviewed unit: base M4 Mac mini; video source identifies base model but retrieved material does not explicitly confirm SSD/RAM.
Tested models
Llama 3.2 1B
Review by Alex Ziskind
See tests & buying guide
Creator identifies Mac mini M4 Pro; reviewed memory, CPU/GPU bin and SSD not disclosed in the accompanying writeup.
Tested models
Gemma 4 31B
Review by Andrej Baranovskij / Katana ML
See tests & buying guide
Reviewed setup: five M2 Ultra Mac Studios,64 GB memory each. Later section tests one 64 GB Studio using Ollama.
Tested models
Llama 3.3 70B
Review by NetworkChuck
See tests & buying guide
Reviewed unit: M3 Ultra 32-core CPU,80-core GPU,512 GB unified memory; macOS 26.5.1. Historical 512 GB configuration is confirmed by reviewer, while current archived Apple page lists 96/256 GB.
Tested models
Qwen3.8 27B · Qwen3.5 122B-A10B
Review by NetworkChuck
See tests & buying guide
Reviewed unit:36-core CPU,80-core GPU,256 GB memory; macOS 27.0; Apple review loan.
Tested models
Qwen3.8 27B · Gemma 4 31B
Review by NetworkChuck
See tests & buying guide
Reviewed unit described as M4 Max MacBook Pro 128 GB,16 CPU cores,4 TB SSD; screen size not confirmed in retrieved video metadata.
Tested models
Phi-4
Review by IndyDevDan
See tests & buying guide
Pre-production Framework Desktop, Max+395; Linux/Fedora ROCm 7 toolbox. Capacity not explicitly stated in accessible video description.
Tested models
Qwen-Image · Wan 2.2
Review by Donato Capitella
See tests & buying guide
128 GB; 96 GB GPU /32 GB CPU memory allocation; Windows LM Studio.
Tested models
gpt-oss-120b · Llama 3.3 70B
Review by ServeTheHome / Patrick Kennedy
See tests & buying guide
128 GB, Windows 11, llama.cpp; compared CPU and iGPU execution with EVO-T1.
Tested models
gpt-oss-20b · Qwen3.5 35B · Gemma 4 26B
Review by Country Boy Computers
See tests & buying guide
96 GB DDR5, Windows 11, llama.cpp.
Tested models
gpt-oss-20b · Qwen3.5 35B · Gemma 4 26B
Review by Country Boy Computers
See tests & buying guide
128 GB/2 TB Windows 11Pro, Performance mode.
Tested models
Qwen3-Next 80B
Review by ServeTheHome / Ryan Smith and Patrick Kennedy
See tests & buying guide
HX470 review unit, LM Studio; RAM and SSD absent from accessible description.
Tested models
Gemma4 E4B
Review by ToviWorks - SmartPhone Tunner
See tests & buying guide
HP Z2 Mini G1a,128 GB,Linux,Fedora toolbox; tuned kernel/memory allocation.
Tested models
GLM4.5-Air106B · Qwen3-235B
Review by Donato Capitella
See tests & buying guide
Single128 GB GX10 with vLLM for first test; second test used two128 GB GX10s connected over QSFP.
Tested models
Qwen3.6-35B-A3B · MiniMax M2.7
Review by Techno Tim
See tests & buying guide
Two Dell-supplied128 GB systems for independent workflow/model tests; do not assume models were split across both.
Tested models
gpt-oss-120b · gpt-oss-20b
Review by ServeTheHome / Patrick Kennedy
See tests & buying guide
128 GB M5; reviewer compared performance modes and Qwen inference across StrixHalo systems.
Tested models
Qwen3.6-35B · Qwen3.8-27B
Review by ServeTheHome / Patrick Kennedy
See tests & buying guide
Single DGX Spark; exact SSD and software build not established in indexed video description
Tested models
Qwen 3.6 27B
Review by Alex Finn
See tests & buying guide
Orin Nano Super running Jetson containers, Ollama, LlamaIndex and Streamlit; storage capacity not confirmed
Tested models
Llama 3.2 (size not specified in video description)
Review by Bijan Bowen
See tests & buying guide
T5000 developer kit with 128 GB and included 1 TB SSD; STH describes short test window using workloads close to NVIDIA reference material
Tested models
Llama 3.1 8B
Review by STH Labs / ServeTheHome
See tests & buying guide
Single RTX 3060 12 GB; host CPU, RAM and operating system not confirmed
Tested models
Qwen3 14B
Review by Chris Ortiz AI Technology Business
See tests & buying guide
RTX 3090 24 GB in creator comparative GPU test; host CPU/RAM not confirmed
Tested models
Qwen3.6-27B
Review by Tech-Practice
See tests & buying guide
GamersNexus comparison bench; exact LLM host CPU/RAM not confirmed. See the original test method.
Tested models
DeepSeek Llama 8B Distil (review label)
Review by GamersNexus / Steve Burke
See tests & buying guide
GamersNexus comparison bench; exact LLM host CPU/RAM not confirmed. See the original test method.
Tested models
DeepSeek Llama 8B Distil (review label)
Review by GamersNexus / Steve Burke
See tests & buying guide
GamersNexus comparison bench; exact LLM host CPU/RAM not confirmed. See the original test method.
Tested models
Llama 3.3 70B
Review by GamersNexus / Steve Burke
See tests & buying guide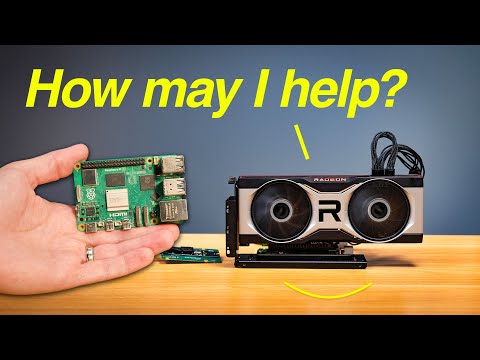
Raspberry Pi 5 plus external RX 6700 XT; patched amdgpu kernel and llama.cpp Vulkan; not an ordinary plug-and-play desktop configuration
Tested models
Llama 3.2 3B Instruct
Review by Jeff Geerling
See tests & buying guide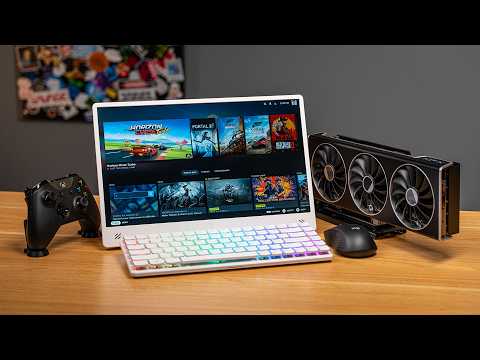
Raspberry Pi 500+ 16 GB using M.2-to-OCuLink dock, external PSU, custom Linux kernel patch and Vulkan. Benchmark is specific to this unusual host.
Tested models
Llama 3.2 3B Instruct · Qwen2.5 14B Instruct
Review by Jeff Geerling
See tests & buying guideThese are different tests, not a shared benchmark. Use the review methods before comparing speed.
Select up to three cards above to build your comparison.
We link the official product or technical specification page. The reviewed unit is separate from the maximum configuration offered for sale.
Each profile links a YouTube review and its supporting source. We record named models, engine and quantization only when the source identifies them. We do not claim to have independently benchmarked these machines.
Unknown settings, software gaps and setup difficulty matter. Results from different reviews cannot be compared as a controlled speed ranking. Our buying advice is an editorial interpretation of the cited evidence.
Owner reports add context when available, but are not lab benchmarks. Share your exact machine, model file, engine, context and outcome so others can reproduce your result.
Share a hardware test →