On this page
What an embedding model doesEmbeddings are not the final answerHow to choose an embedding modelBuild a search testAvoid a hidden mistakeSearch by meaning with a small exampleDo I need a large embedding model?SourcesThe writing model cannot use evidence that search failed to find. Test the embedding model and search system separately.
Test document search before the chat model
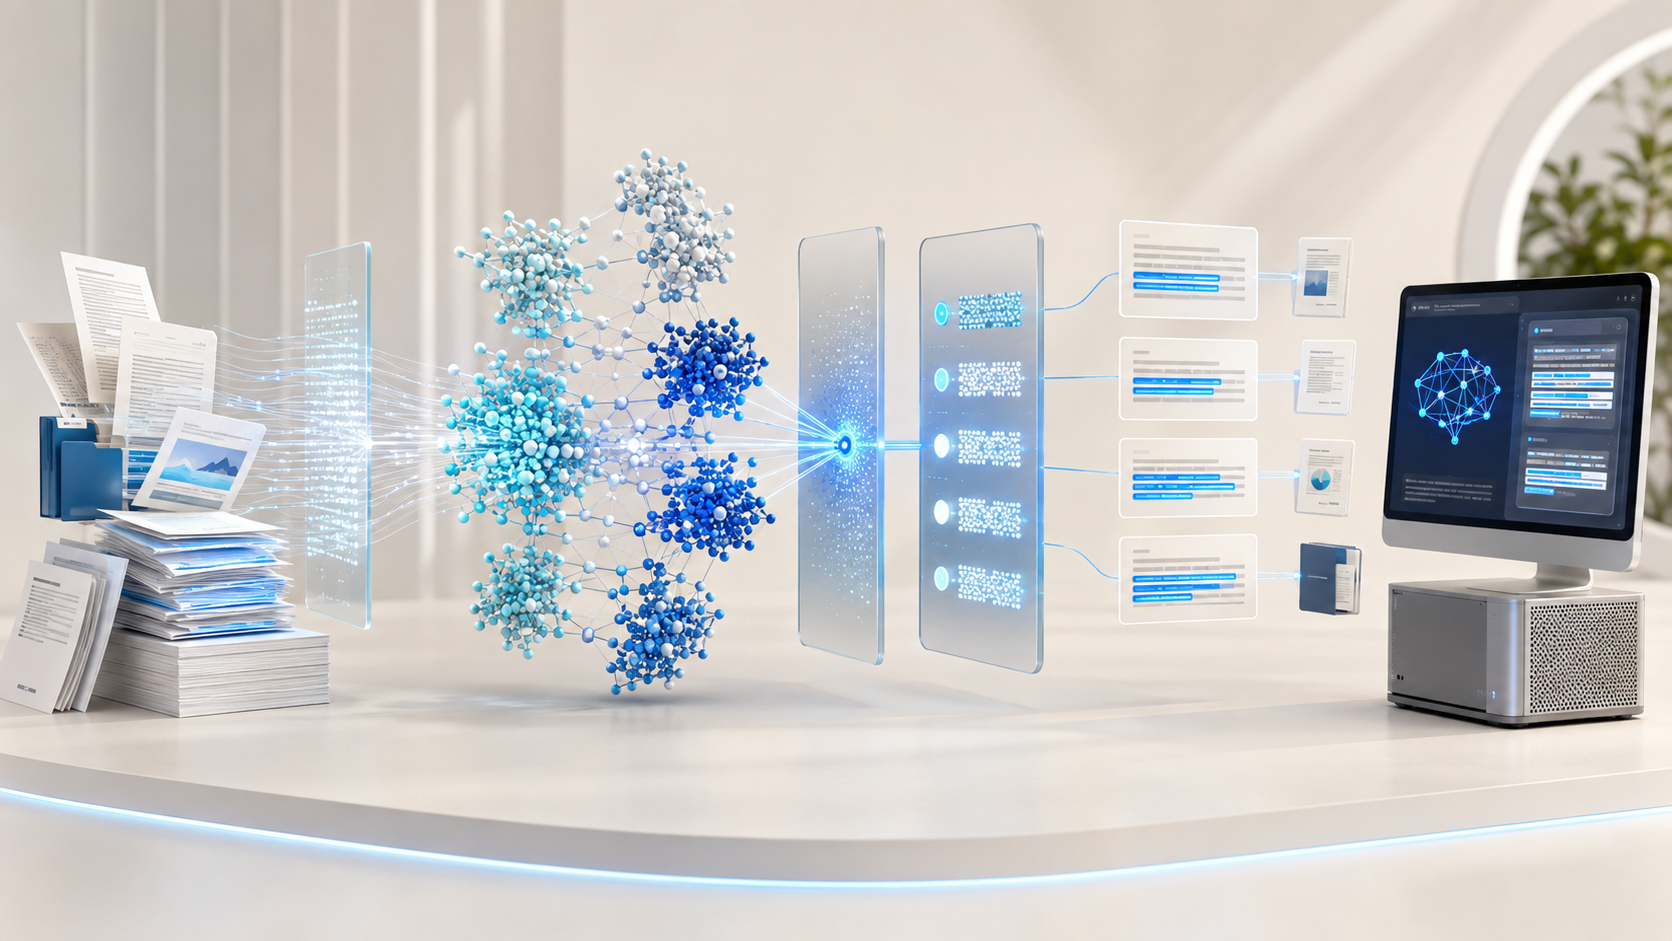
An embedding model does not write the final answer. It helps the system find document passages with a meaning close to the user's question.
- 1
Prepare thirty questions
For each question, mark the exact passage that contains the answer.
- 2
Build the search index
Use one embedding model for both the document passages and the user questions.
- 3
Search without generating
View the top five passages returned for every question. Do not ask the writing model to answer yet.
- 4
Count useful results
Record whether the correct passage appears first, in the top three, or in the top five.
- 5
Improve and repeat
Change one thing at a time, such as the embedding model or passage length. Build a new index after changing the embedding model.
- The correct passage appears near the top for most known questions.
- Questions with no answer do not return misleading evidence.
- The embedding model name and version are saved with the index.
Here is what matters, why it matters and how to check it on your own setup.
What an embedding model does
An embedding model turns text into a list of numbers called a vector. Text with a similar meaning should have vectors that sit close together.
The system saves a vector for each document piece. It also makes a vector for the user's question. It then looks for the closest matches.
Embeddings are not the final answer
The embedding model finds useful passages. A different model reads those passages and writes the final answer.
If the wrong passages are found, even a powerful writing model may give a weak or made-up answer.
How to choose an embedding model
- Language: choose a multilingual model when your files use several languages.
- Type of work: legal, code, science, and general writing may search differently.
- Text length: make sure long pieces are not cut off.
- Size: larger vectors use more storage and memory.
- License and support in your local AI tools.
- Results on your own questions.
Build a search test
- Create at least 30 real questions.
- Mark the correct source passage for each question.
- Check whether it appears in the top 1, top 3, and top 5 results.
- Include short forms, different wording, and multiple languages.
- Include questions with no answer.
- Test document size and embedding choice separately.
Avoid a hidden mistake
Do not create document vectors with one embedding model and question vectors with another. Their number systems are not the same.
Save the model name and version with the search index. Build a new index and test again whenever the embedding model or text process changes.
Search by meaning with a small example
Take two short passages: one about school fees and one about school opening hours. An embedding model turns each passage into a list of numbers. It also turns the question into numbers. The search system compares them to find a close match. It does not write the final chat answer.
Ask about fees using different words from the passage. Check whether the right passage appears first. Repeat with the opening-hours question. Add a question about transport that neither passage answers. Then test longer passages and the languages your readers use.
Never mix document vectors from one embedding model with question vectors from another. Rebuild the index after changing the model.
Do I need a large embedding model?
Not always. Compare search results on your own questions. A smaller model that finds the right passage reliably may be the better choice for your computer.
Words you may see in this guide
- RAM
- The working memory used by your computer and apps.
- VRAM
- The memory on a dedicated graphics card. Shared graphics may use system RAM.
- Context
- The text and other input the model can use for its current answer.
- Quantization
- A way to make model weights smaller. It can change memory use and answer quality.
- Engine
- The software that loads the model and runs it.
- RAG
- A workflow that finds useful document passages before asking a model to answer.
- Benchmark
- A repeatable test. A result is useful only when you know the setup and task.
Official facts and real user evidence
Official documentation supports product and model facts. Community discussions show real setups, failures, and questions. A community result is supporting evidence, not a promise that another computer will perform the same way.
Watch a real test. Check what fits your computer.
See practical local AI tests from DeviceTerra, then use MamiLens to build a hardware-aware shortlist for your own setup.
This guide is educational. Model software, licenses, and hardware support can change. Check official sources before an important deployment.