On this page
Model, engine, and app are differentOllama and LM Studiollama.cpp and MLX LMvLLM and SGLangHow to compare enginesThe engine is the bridgeCan I change engines later?SourcesThere is no fastest engine for every job. Choose by hardware, model type, number of users, and how much setup you can manage.
Choose an engine in five minutes
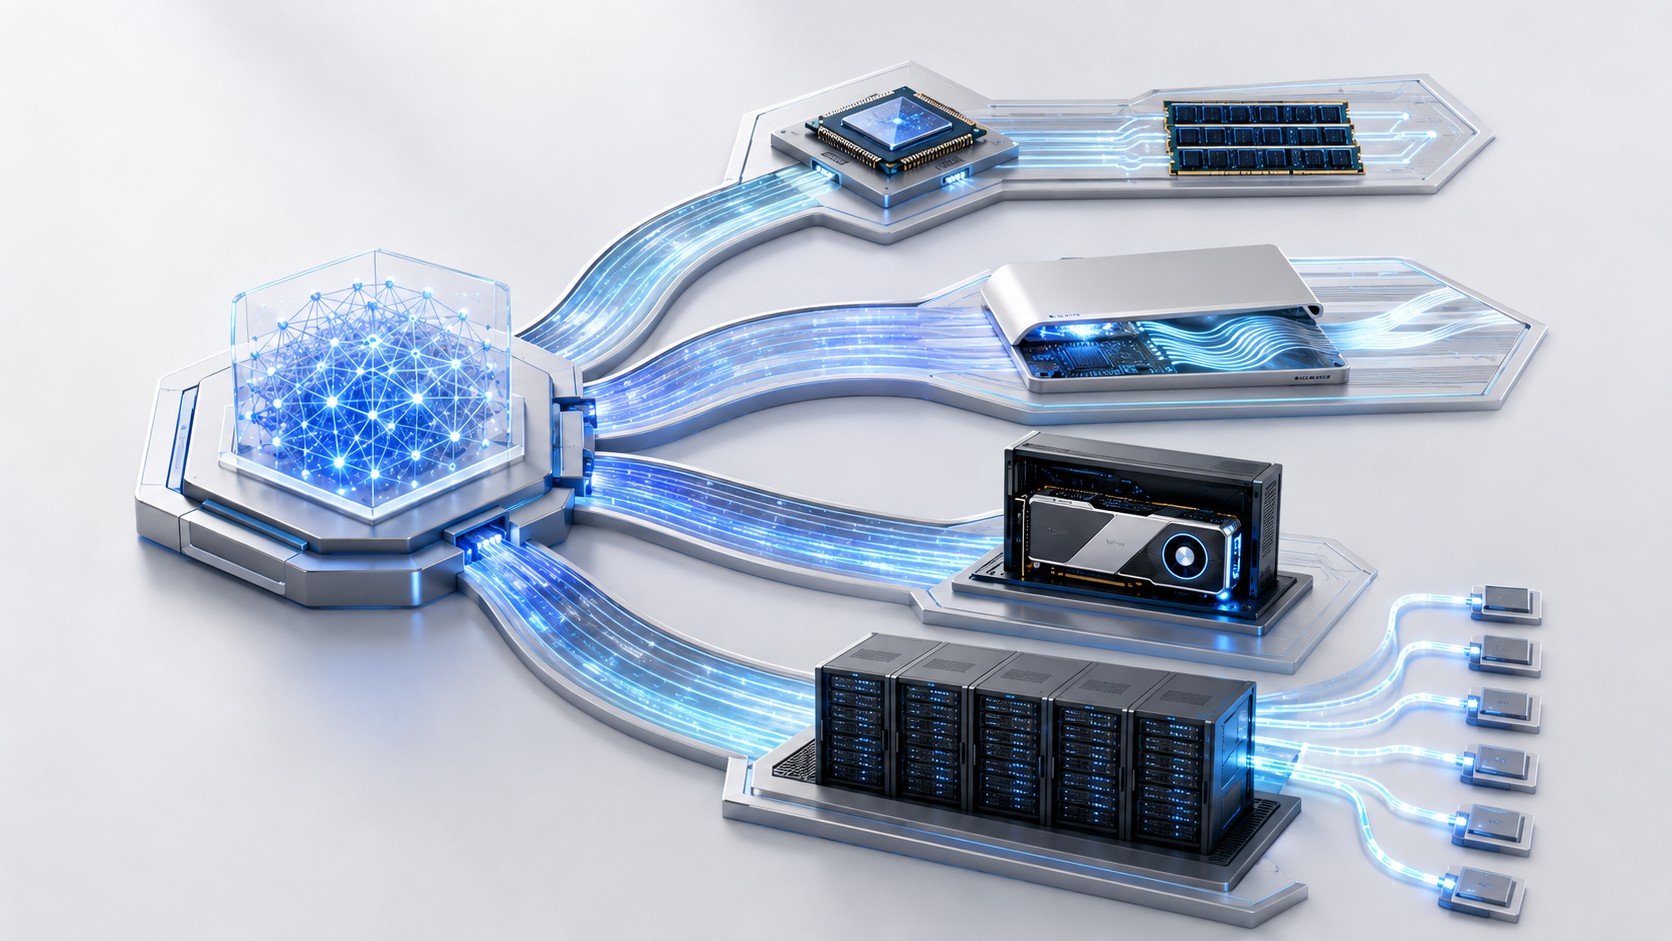
The model is the file that learned patterns. The engine is the software that opens the file and performs the calculations. Choosing an engine is like choosing the right player for a media file.
- 1
Name the user
Decide whether this is for one beginner, one developer, or many people using a shared server.
- 2
Name the hardware
Record the operating system, CPU, GPU, RAM, and VRAM.
- 3
Name the model format
Check whether the model is GGUF, MLX, or another format.
- 4
Use the simplest fit
Try LM Studio for a visual desktop, Ollama for a simple local service, llama.cpp for detailed GGUF control, or a server engine for many users.
- 5
Test one model
Measure setup time, memory, speed, and errors. Do not install several engines without a reason.
- The engine supports the exact model format and hardware.
- The setup matches the number of users.
- You can explain why this engine was chosen.
Here is what matters, why it matters and how to check it on your own setup.
Model, engine, and app are different
The model is the learned data that produces answers. The engine is the software that loads the model and does the math. The app is the screen, command line, or service you use.
Some products combine these parts. Knowing the difference helps you compare them fairly.
Ollama and LM Studio
Ollama makes it easy to download models, run commands, and give other apps a local AI service. It is a strong starting point for developers and simple automations.
LM Studio gives you a visual desktop app. It is useful for finding models, changing settings, and comparing results without many commands.
llama.cpp and MLX LM
llama.cpp is a flexible engine that works across many CPUs and GPUs. It supports GGUF, a common local model file type, and many smaller quantized files.
MLX LM is made for Apple Silicon Macs. It uses Apple's shared memory design and is useful for Mac-focused projects.
vLLM and SGLang
vLLM and SGLang are built mainly for serving many requests on strong GPUs. They focus on sharing hardware well when several people use the model at the same time.
They may be too complex for one person using a laptop. Use them when your tests show that several users need the service.
How to compare engines
- Use the same model file and settings.
- Use the same prompt and answer length.
- Measure load time, first-word time, total speed, and memory.
- Test one user and the number of users you expect.
- Check answer quality for hidden differences.
- Choose the easiest reliable engine when speed is close.
The engine is the bridge
A model file is like a set of learned instructions. The engine loads that file and uses your computer to produce an answer. A chat app may sit above the engine and provide buttons, conversation history and document features. These are different parts, even when one download includes several of them.
Choose the engine before downloading a large file. Confirm that it supports your operating system, exact model format and graphics path. Start with a small model. Check that it loads and answers a simple question before connecting another app.
Support for a model family does not mean support for every file, newer architecture or smaller weight format in that family.
Can I change engines later?
Yes, but you may need another file format. Save your prompts and test again. A change in engine or settings can change memory use and output.
Words you may see in this guide
- RAM
- The working memory used by your computer and apps.
- VRAM
- The memory on a dedicated graphics card. Shared graphics may use system RAM.
- Context
- The text and other input the model can use for its current answer.
- Quantization
- A way to make model weights smaller. It can change memory use and answer quality.
- Engine
- The software that loads the model and runs it.
- RAG
- A workflow that finds useful document passages before asking a model to answer.
- Benchmark
- A repeatable test. A result is useful only when you know the setup and task.
Official facts and real user evidence
Official documentation supports product and model facts. Community discussions show real setups, failures, and questions. A community result is supporting evidence, not a promise that another computer will perform the same way.
Watch a real test. Check what fits your computer.
See practical local AI tests from DeviceTerra, then use MamiLens to build a hardware-aware shortlist for your own setup.
This guide is educational. Model software, licenses, and hardware support can change. Check official sources before an important deployment.