On this page
Running is only the first testBuild a small test setWhat to measureSet a pass markKeep checking after launchA correct-looking answer can still failHow many tests are enough?SourcesA model is useful only when it gives good enough answers, at a useful speed, with an acceptable level of risk.
Create a small reliability test
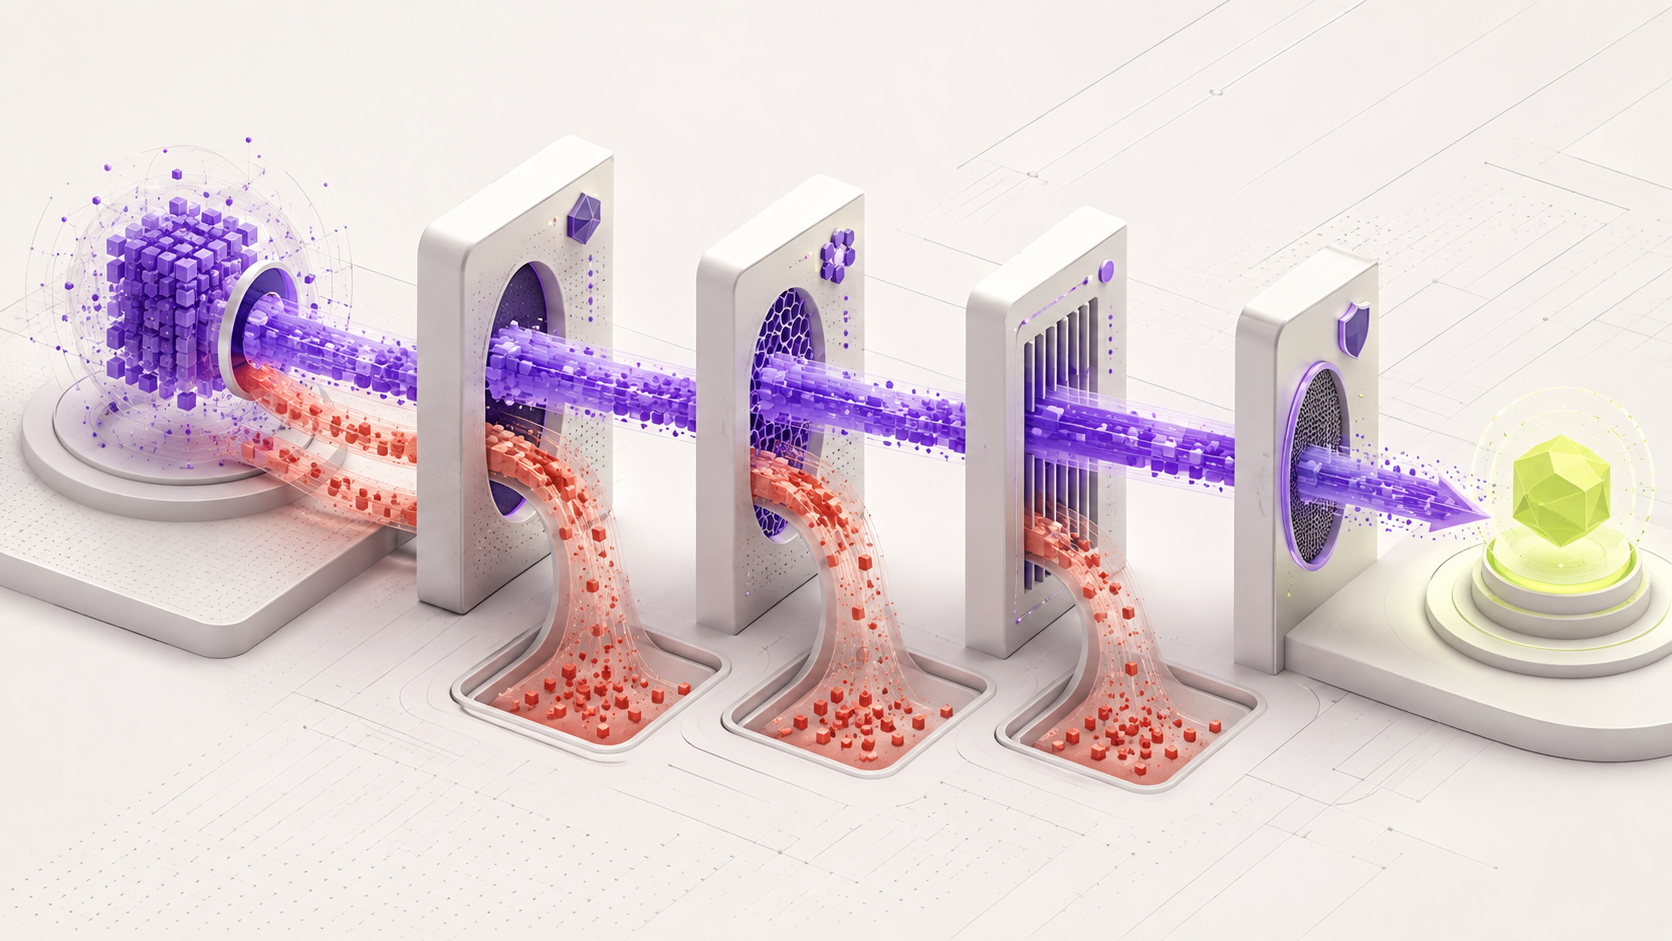
A model opening successfully is not proof that it can do your job. Reliability means it keeps giving useful answers across many real examples.
- 1
Collect twenty examples
Remove names and secrets. Include normal tasks, hard tasks, and questions that should not be answered.
- 2
Write the correct result
Before running the AI, write the answer or rule you will use to score each example.
- 3
Set a pass mark
For example, decide that the model must pass at least 17 of 20 examples and must not fail any safety question.
- 4
Run every example
Use the same prompt, settings, and model version. Record the answer and waiting time.
- 5
Review failures
Group failures into wrong facts, broken format, missing evidence, slow answer, and unsafe answer.
- The pass mark was written before testing.
- Every result can be checked again.
- You can explain why the model passed or failed.
If something goes wrong
- If the result changes often, run the same test more than once.
- If the prompt changes, begin a new test version instead of mixing the results.
Here is what matters, why it matters and how to check it on your own setup.
Running is only the first test
A model may open and answer a question, but that does not prove it can do your job. It may be slow, ignore instructions, invent facts, or give a different answer each time.
Compatibility tells you the model fits the computer. Reliability tells you whether you can depend on it.
Build a small test set
Collect 20 to 30 examples from the real job. Remove private details. Include easy, hard, unclear, and should-refuse questions.
Write the correct answer or scoring rule before you test. This keeps you from choosing a model only because one answer looks impressive.
What to measure
- Correctness: is the main answer right?
- Evidence: can the answer be checked?
- Instruction following: did it use the requested format?
- Speed: is the waiting time acceptable?
- Consistency: does it work across many examples?
- Safety: does it refuse when it should?
Set a pass mark
Decide what the model must achieve before the test. A drafting tool may allow human editing. A system that affects money, health, safety, or legal work needs much stronger checks.
If the model does not pass, try a better prompt, a different model, or a smaller job. Do not hide the failure.
It is safer to say “I do not know” than to invent an answer.
Keep checking after launch
- Save the model name and version.
- Record important settings and prompts.
- Collect failures from real users.
- Test again after any model, prompt, or software update.
- Keep a way to return to the last working version.
A correct-looking answer can still fail
Suppose a model writes a customer email that sounds polite but promises a refund your policy does not allow. The text looks good, yet the business result is wrong. Testing must check the decision and facts, not only spelling and tone.
Create examples of normal requests, difficult requests and requests that need a person. Write down the expected result first. Score each answer for facts, missing details and actions it should not take. Save failures so you can test them again.
Do not let the model grade itself as the only judge. A person needs to check important answers against a trusted source.
How many tests are enough?
There is no magic count. Begin with a small set that covers real situations. Add every serious failure. Higher-risk work needs deeper tests and human review before use.
Words you may see in this guide
- RAM
- The working memory used by your computer and apps.
- VRAM
- The memory on a dedicated graphics card. Shared graphics may use system RAM.
- Context
- The text and other input the model can use for its current answer.
- Quantization
- A way to make model weights smaller. It can change memory use and answer quality.
- Engine
- The software that loads the model and runs it.
- RAG
- A workflow that finds useful document passages before asking a model to answer.
- Benchmark
- A repeatable test. A result is useful only when you know the setup and task.
Official facts and real user evidence
Official documentation supports product and model facts. Community discussions show real setups, failures, and questions. A community result is supporting evidence, not a promise that another computer will perform the same way.
Watch a real test. Check what fits your computer.
See practical local AI tests from DeviceTerra, then use MamiLens to build a hardware-aware shortlist for your own setup.
This guide is educational. Model software, licenses, and hardware support can change. Check official sources before an important deployment.