On this page
The real problem is a pipelineCheck the PDF before blaming AITest retrieval by itselfChunk size is not one magic numberMake answers checkableApply permissions before searchBuild a production testChoose the writing model lastCheck a citation like a reader wouldCan it answer across several PDFs?SourcesTest the document pipeline in order: text extraction, retrieval, evidence, answer, and permissions. A larger chat model cannot repair a missing page.
Here is what matters, why it matters and how to check it on your own setup.
The real problem is a pipeline
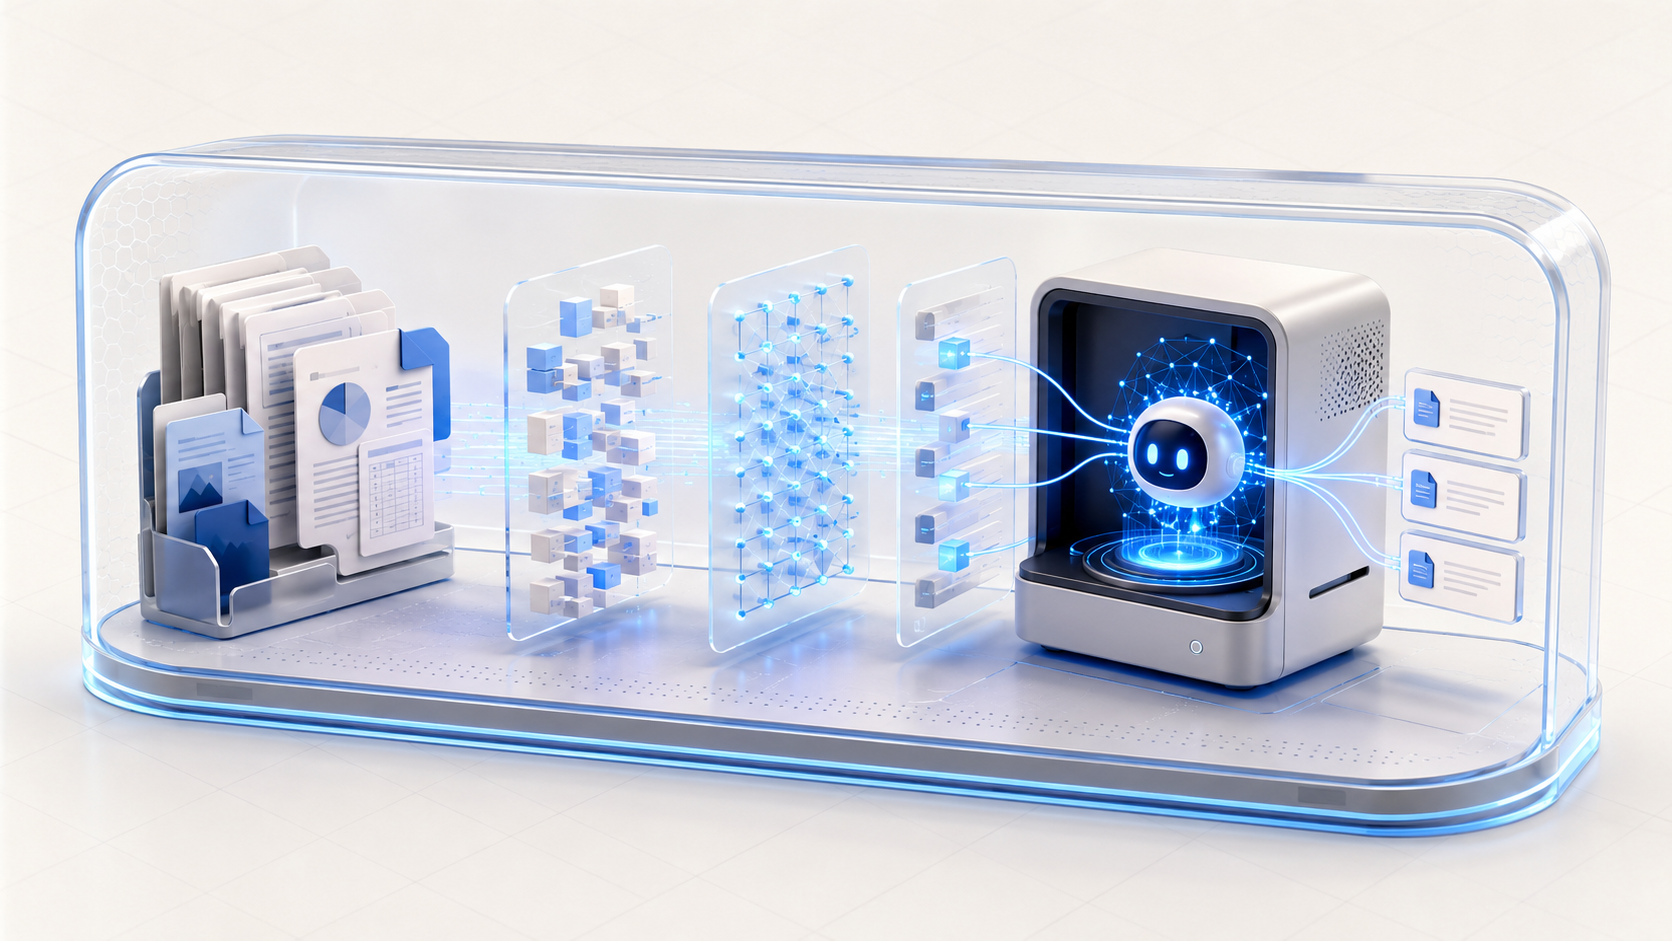
A PDF assistant must read the file, break it into useful parts, find the right part, and give it to the writing model. Asking only for the best PDF model misses most of the system.
If an earlier step fails, the final answer can be wrong even when the writer is strong. Open WebUI discussions include users who uploaded a PDF but received no useful content and others who improved retrieval by changing context or search settings.
Check scans, columns, tables, and OCR
Measure top 1, top 3, and top 5
Keep file and page details
Allow a clear not found result
Filter before retrieval
Check the PDF before blaming AI
Try to select and copy a sentence. If you cannot, the page may be an image and needs optical character recognition, called OCR. Small text, handwriting, stamps, and poor scans can still create errors.
Tables and multi-column pages can be extracted in the wrong order. Open the extracted text and compare it with the original page before changing the model.
Test retrieval by itself
Create thirty questions and mark the exact passage that answers each one. Ask the search system for the closest passages without asking the chat model to write an answer.
Record whether the correct passage appears first, in the top three, or in the top five. If it is missing, change chunking, embedding, document cleaning, or query settings before changing the writer.
Strong and easy to cite
Good for many tasks
May add distracting text
The writer never received the evidence
Chunk size is not one magic number
Small chunks can find exact details but lose surrounding meaning. Large chunks keep context but may mix several topics and use more prompt space.
Forum users report different results with overlap, Top K, reranking, and embedding models. Use those settings as test ideas, not universal answers.
A setting is useful when it finds more correct passages on your own known questions.
Make answers checkable
- Show the source filename and page number.
- Display the exact passage used.
- Separate evidence from the model's explanation.
- Let the user open the original page.
- Use not found when evidence is weak.
- Keep a record of the model, prompt, and retrieval settings.
Apply permissions before search
Do not retrieve a private passage and hide it later. Check the user's role before searching. Search only document groups that the user is allowed to see.
Keep files, extracted text, embeddings, chats, and backups under the same data rules. A local writer does not make cloud OCR, storage, or analytics private.
Build a production test
- Ten direct fact questions.
- Five questions needing two passages.
- Five questions about tables, dates, or numbers.
- Five questions with no answer in the files.
- Three questions from old or conflicting documents.
- Two document prompt-injection attempts.
- Permission tests for every user role.
Choose the writing model last
After retrieval works, compare an 8B and a 14B instruction model on the same evidence. The smaller one may handle direct answers. The larger one may help with joining passages or following strict formats.
Choose the smallest model that reaches the pass mark. This keeps the system faster and easier to serve.
Check a citation like a reader would
Ask a question about a rule on a known page. The reply should name the file and page and show the supporting passage. Open that passage yourself. If it says something different, the answer fails even if the wording sounds confident.
Keep a question sheet with expected pages. Include two similar rules and an old version of a policy to test confusion. Decide which document is current. Add a question whose answer is missing.
Search permission must be checked before retrieving private passages. Hiding a passage after the model has seen it is too late.
Can it answer across several PDFs?
Yes, with a suitable search workflow, but test conflicting versions and claims that need more than one passage. Show separate sources when the answer combines evidence.
Words you may see in this guide
- RAM
- The working memory used by your computer and apps.
- VRAM
- The memory on a dedicated graphics card. Shared graphics may use system RAM.
- Context
- The text and other input the model can use for its current answer.
- Quantization
- A way to make model weights smaller. It can change memory use and answer quality.
- Engine
- The software that loads the model and runs it.
- RAG
- A workflow that finds useful document passages before asking a model to answer.
- Benchmark
- A repeatable test. A result is useful only when you know the setup and task.
Official facts and real user evidence
Official documentation supports product and model facts. Community discussions show real setups, failures, and questions. A community result is supporting evidence, not a promise that another computer will perform the same way.
Watch a real test. Check what fits your computer.
See practical local AI tests from DeviceTerra, then use MamiLens to build a hardware-aware shortlist for your own setup.
This guide is educational. Model software, licenses, and hardware support can change. Check official sources before an important deployment.